Advanced Threat Modeling: Identities, Trust Boundaries, and Attack Chains
Imagine a security review where nobody finds a “critical vulnerability” in the scanner, the code review looks clean, and the deployment proceeds as usual. Two weeks later, someone discovers that an internal service accepts calls from the control plane with a short-lived token that, in practice, opens lateral access to data from multiple tenants. The problem was not hidden in some exotic line of code. It was hidden in the system design.
This is where threat modeling separates mature defensive engineering from decorative checklists. In experienced teams, modeling threats is not about filling STRIDE into a spreadsheet, nor drawing a DFD to satisfy audit. It is about decomposing the system the way an attacker sees it: identities, trust boundaries, paths of influence, automation surfaces, external dependencies, and, above all, plausible ways to turn an operational assumption into real impact.
In this article, the focus is not “what threat modeling is.” The focus is how to use threat modeling in an advanced way to find the flaws that almost always slip through: identity chains, control plane versus data plane, integration abuse, implicit trust boundaries, and risks that emerge when the system makes requests, signs URLs, or delegates decisions to components nobody truly modeled.
Useful threat modeling does not just produce a list of threats. It produces prioritized attack hypotheses, architecture decisions, and measurable blast-radius reduction.
The real problem: almost everyone models components, but few model capabilities
The most common mistake in superficial threat-modeling exercises is to focus on diagram boxes and forget what actually matters: which capabilities each actor, process, token, queue, serverless function, or managed service receives when it crosses a trust boundary.
In modern environments, the central question is rarely “where is the web server?” The useful question is:
- who can invoke this component;
- under which identity it executes;
- which resources it can reach that the original user cannot;
- which decisions are taken implicitly by infrastructure, SDK, proxy, gateway, or managed service;
- what happens if someone turns this component into an unintended proxy.
When the model captures capability, not just topology, more relevant threats emerge:
- SSRF that becomes access to cloud metadata and then temporary credentials;
- a sharing token with scope that is too broad becoming horizontal data exposure;
- a “read-only” integration that in practice carries listing, deletion, or write permissions;
- a control plane that trusts internal events without sufficient contextual authentication;
- an agent/fetcher automation that accepts arbitrary URLs and inherits the host’s internal access.
Advanced threat modeling starts with three maps, not a list of threats
For more sensitive systems, a minimally useful model usually requires three complementary views.
1. Data-flow map
The DFD is still valuable, but only if it shows processes, stores, flows, and trust boundaries that actually matter. It is not the “pretty” PowerPoint diagram. It is the diagram that makes clear where data changes context.
2. Identity and capability map
List humans, workloads, service accounts, roles, SAS URLs, API keys, OAuth tokens, signed URLs, webhooks, and transitive permissions. In cloud and SaaS environments, this view often explains more incidents than the network diagram.
3. Abuse-path map
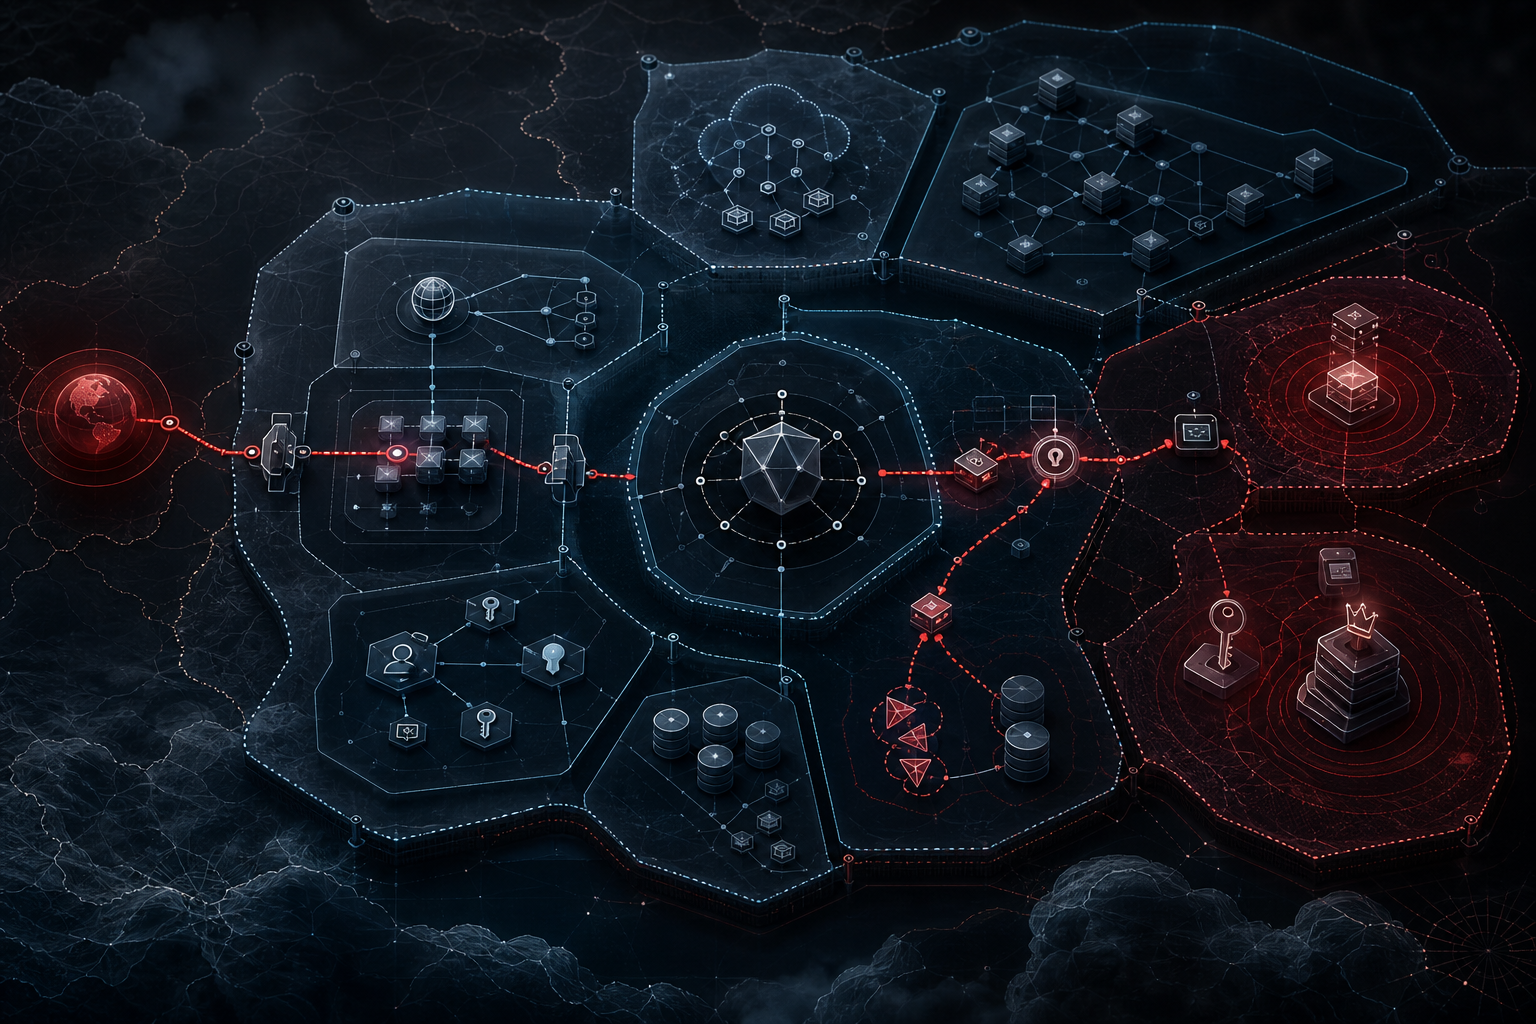
Here the goal is to answer: “if I control X, what is the next plausible pivot?” That brings the exercise closer to a practical attack graph, even without formalizing everything as an attack tree.
Short example:
User-controlled input
  -> import/fetch service
     -> server-side request to an arbitrary destination
        -> internal endpoint / metadata / admin API
           -> temporary credential / secret / backend token
              -> expanded access to storage / queues / internal APIs
                 -> exfiltration, modification, or lateral movement
Notice that the initial vulnerability may be simple. The real impact appears because the model captured the capabilities accumulated along the chain.
STRIDE is still useful, but by itself it is rarely enough
Microsoft’s approach remains relevant because it enforces discipline in design analysis. The SDL documentation and the Threat Modeling Tool are still useful for structuring reasoning, especially with STRIDE by element. But in current systems, STRIDE alone usually has two operational limitations:
- it helps classify threats, but does not necessarily reveal the chaining path between them;
- it tends to lose business context, identity context, and operational abuse context when used mechanically.
In practice, mature teams combine STRIDE with more aggressive questions:
- which trust assumption, if wrong, collapses the design?
- which component makes requests on behalf of third parties?
- which secret or token exists only for operational convenience?
- where can a temporary permission be reused outside its intended case?
- which component sees more than it should by default?
- which internal event is not authenticated, signed, or bound to the original context?
This is a good point to use STRIDE as grammar, not as a cognitive limit.
Real example 1: Capital One and what traditional modeling often failed to capture
The Capital One case became a reference because it showed that, in cloud, an apparently “local” application flaw can turn into a massive incident when combined with implicit infrastructure identity.
Public sources on the case, including Capital One’s official incident page and later court filings, describe a scenario in which the attack occurred in March 2019, with impact on approximately 100 million individuals in the United States and 6 million in Canada. Technical literature on the case converged on the same chain: SSRF against an exposed component, access to the EC2 metadata service, theft of temporary credentials associated with the instance role, and use of those credentials to reach data in S3.
The value of the example is not to retell the intrusion. It is to observe what a competent threat model should have highlighted:
- the vulnerable component could make server-side requests;
- the host had access to the metadata service;
- the instance identity had permissions beyond what was strictly necessary;
- subsequent use of the credentials would appear, at least in part, as legitimate traffic from an authorized principal.
Translated into threat modeling, it is not enough to mark Information Disclosure on the web server. You need to model:
- trust boundary: external input controlling server-side output;
- capability jump: the application inheriting the instance identity;
- blast radius: a role with excessive scope for sensitive storage;
- detection gap: use of a valid credential obtained through an improper path.
If the model does not make explicit the question “what can this service reach by virtue of running here?”, it misses exactly the part that matters in cloud.
Real example 2: Microsoft’s SAS token incident and the modeling of delegation
Another instructive example is the incident reported by Microsoft itself in 2023 after coordinated disclosure by Wiz. According to the MSRC, a URL with an overly permissive Shared Access Signature was published in a public GitHub repository, allowing access to an internal storage account. Microsoft stated there was no customer impact, but the case is excellent for threat modeling because it shows how “temporary sharing” often escapes the security design.
What should appear in an advanced model?
- a SAS token is a delegated-capability secret, not just a link;
- the risk is not only the leak of the artifact, but the scope of resources, permissions, and time window it carries;
- a read, list, write, or delete token completely changes the blast radius;
- detection mechanisms may fail if the organization treats SAS as an operational exception rather than a production credential.
In many environments, signed URLs, presigned URLs, secret webhooks, and export links stay outside the threat model because “they are not classic credentials.” That is a structural mistake. Anything that delegates access must enter the identity and capability map.
Contemporary example: agents, fetchers, and SSRF as an emergent capability
A more recent theme is the surface created by tools that fetch on behalf of the user or the agent. In 2026, public discussions in issues on the modelcontextprotocol/servers repository drew attention to the default risk of fetch servers exposed to autonomous agents: access to private IPs, cloud metadata, unsafe redirects, DNS validation gaps, and lack of streaming limits.
It is important to be precise here: the issue itself highlights that this is about hardening and defense in depth, not necessarily confirmed exploitation in a specific deployment. Even so, for threat modeling, the point is central.
When a component accepts an arbitrary URL and performs the request with the host’s connectivity, it becomes an SSRF primitive. If it also follows redirects automatically, reads the entire response before truncating, or fails to pin validated DNS resolution, the risk grows.
In agent-based systems, the question stops being only “can the user open this URL?” and becomes:
- can the agent reach destinations the user cannot;
- does the fetcher inherit access to localhost, RFC1918 ranges, link-local addresses, or metadata endpoints;
- can a public redirect lead to an internal target;
- does the host’s network policy actually reduce the blast radius of an improper fetch.
This kind of threat is born from system design, not from an isolated CVE. It is exactly the type of risk threat modeling should anticipate.
How to model trust boundaries in the way that matters
Beginner threat modeling often treats a trust boundary as a line between the Internet and the backend. In real operations, that is far too simplistic. Modern systems have several smaller and more dangerous trust boundaries:
- the boundary between an authenticated user and a service holding backend credentials;
- the boundary between data plane and control plane;
- the boundary between tenant and shared platform;
- the boundary between custom code and a managed service;
- the boundary between a workload and metadata or secret manager;
- the boundary between a “trusted” internal event and an actually authenticated event.
A practical rule: whenever something crosses a boundary and gains a new capability, it deserves special attention in the model.
Operational checklist of useful boundaries
- external input that triggers server-side action;
- a service that signs links, issues tokens, or delegates permissions;
- an asynchronous workflow that consumes events without revalidating context;
- a third-party integration with callback or webhook;
- a function or job that can see data from multiple tenants;
- an internal tool that “only helps operations” but talks to privileged APIs.
A practical way to conduct advanced threat modeling
Instead of trying to model everything with the same depth, a pragmatic approach works better.
Phase 1: impact-guided decomposition
Start with the flows that concentrate the most:
- sensitive data;
- irreversible actions;
- transitive privileges;
- execution on behalf of third parties;
- automation or external integrations.
Phase 2: inventory of identities and delegations
Build a living table with:
- who the principal is;
- how the identity is obtained;
- what the real scope is;
- how it is revoked;
- what the worst impact would be if it leaked or were abused.
Phase 3: abuse hypotheses
For each critical flow, force questions such as:
- what if this input becomes a server-side request?
- what if this token is reused outside the intended case?
- what if an internal event can be forged?
- what if this component answers on behalf of another principal?
- what if a redirect or DNS change bypasses the initial validation?
Phase 4: prioritize by exploit path, not just nominal severity
Not every theoretical threat deserves the same attention. Prioritize by plausible path:
- real prerequisites;
- likelihood of chaining;
- ease of detection;
- blast radius;
- operational mitigation cost versus risk reduction.
Phase 5: validate the model against reality
An outdated threat model creates a false sense of control. Compare it against:
- the architecture actually deployed;
- real IAM roles and policies;
- allowed egress routes;
- secrets and tokens issued in production;
- asynchronous flows and newly added integrations.
A mini example model: document import service by URL
Assume a SaaS product with a feature called “import document by URL.” This type of feature looks trivial and often receives shallow modeling. A better model would be:
Authenticated external actor
  -> public API /imports
     -> server-side fetch worker
        -> document parser
           -> internal storage
              -> indexer / search / downstream processing
Relevant questions:
- does the worker access localhost, private network ranges, or the metadata service;
- are redirects validated at every hop;
- is DNS resolution pinned before connection;
- is there a size limit before the full body is read;
- are content type and protocol restricted;
- can the imported document trigger dangerous parsing or excessive resource consumption;
- does the stored object inherit excessive permissions or visibility;
- does the downstream pipeline treat this content as trusted.
Mitigations that come directly from the model:
- allowlist of schemes and blocking of private or reserved destinations;
- redirect revalidation;
- streaming with byte caps and short timeouts;
- minimal egress network policy;
- worker isolation without access to unnecessary secrets;
- file quarantine until validation.
Notice the difference: instead of a generic “SSRF risk,” the model produces concrete, testable controls aligned with the real flow.
What to detect after the threat model becomes control
Mature threat modeling does not end in recommendations. It informs observability and detection.
Some useful signals derived directly from models like this:
- server-side requests to private ranges, link-local addresses, or rare destinations;
- use of temporary credentials outside the expected profile;
- delegation tokens with excessive scope or validity that lasts too long;
- spikes in storage access by a principal that does not normally list objects;
- callbacks or webhooks with inconsistent origin or signature;
- fetchers following unusual redirect chains;
- control-plane services being called from components meant for the data plane.
This is a frequently neglected point: a good threat model helps choose what is worth logging, alerting on, and hunting for. Without that, telemetry becomes a pile of events with no operational hypothesis behind it.
Limitations that must be recognized
Threat modeling does not replace code review, pentest, tabletop exercises, or telemetry engineering. It also fails when:
- the modeled system does not match the real environment;
- identities and permissions are left out of scope;
- the exercise stops at taxonomy and never reaches the exploit path;
- there is no mechanism to review the model after architectural changes;
- the output never enters the backlog with an owner, priority, and verification step.
In other words: the value of the threat model is not in the workshop, but in how much it changes design, configuration, detection, and continuous validation.
Conclusion: modeling threats is modeling trust decisions
Advanced threat modeling is not a catalog of bad things that could happen. It is the discipline of making explicit the trust decisions the system is already taking silently.
When the exercise is done well, it reveals uncomfortable questions:
- why can this service talk to that?
- why does this token delegate so much?
- why does this component see more than it needs?
- what prevents this flow from becoming a proxy to something more sensitive?
Those questions are more valuable than any generic checklist, because they capture how real attacks happen: not as isolated events, but as chains of poorly placed trust.
If your modeling still revolves around bureaucratically filled-out STRIDE, the next step is not to abandon the method. It is to increase the granularity: map identities, delegations, pivots, and blast radius. From that point on, threat modeling stops being ceremony and becomes what it should have been from the start: security engineering oriented toward plausible attack paths.
References
- Microsoft Security Development Lifecycle — Threat Modeling
- Microsoft Threat Modeling Tool overview
- OWASP Threat Modeling Cheat Sheet
- Threat Modeling Manifesto
- MSRC — overly permissive SAS token incident
- Capital One — 2019 Cyber Incident facts
- In re: Capital One Consumer Data Security Breach Litigation (complaint)
- mcp-server-fetch hardening discussion (Issue #4116)
💜 Enjoyed this content? Support the blog with USDT (TRC20):
TX7obcjHQbDUXb4mGqoASEu1QFTKT2CFGG