Autonomous Pentest Agent: AI, Red Team, and Attack Chains
Quick summary: an autonomous Pentest Agent is not “an LLM running Nmap.” In real operations, the value — and the risk — lies in the agent’s ability to turn partial evidence into hypotheses, choose the next action, maintain operational memory, validate false positives, and stop before going out of scope. This autonomy changes Red Team dynamics because it compresses reconnaissance, enumeration, triage, and reporting cycles, but it also creates a new attack surface: the agent’s own decision chain.
Executive Summary
Pentest automation has always existed. Scanners, enumeration scripts, Nuclei templates, recon pipelines, and tool wrappers were already reducing repetitive work long before LLMs. The difference with the autonomous agent is something else: it starts deciding when to use a tool, why that result matters, which hypothesis should be tested next, and how to turn technical findings into auditable evidence.
This is powerful in Red Team operations because much of the operational time is not spent “exploiting,” but filtering noise: deciding whether a banner is relevant, whether an endpoint deserves fuzzing, whether a 403 response indicates a real control or broken routing, whether a public API suggests BOLA, whether a forgotten subdomain points to takeover, or whether an issue is just expected framework behavior.
Attacker’s View
An experienced offensive operator does not see a Pentest Agent as a “bot that exploits vulnerabilities.” They see it as an OODA cycle accelerator: observe, orient, decide, and act. In corporate environments, whoever shortens that cycle gains an advantage. The agent collects signals, orients hypotheses, decides next actions, and executes low-friction validations in minutes.
The adversarial perspective changes the architecture. A useful agent must reason about probability, cost, and noise. If it finds a portal with SSO, it is not enough to record “login found.” It must ask: is there an exposed tenant? Does the domain reveal Entra ID, Okta, or Google Workspace? Are there public email patterns? Is there a weak DMARC policy that enables a pretext? Does the certificate suggest a legacy environment? Does any documentation point to the same system?
That is the difference between superficial automation and offensive autonomy: the agent does not execute a linear checklist. It prioritizes paths where external information reduces uncertainty. Instead of launching indiscriminate fuzzing, it identifies where an endpoint, a header, an error response, or an authentication pattern suggests a realistic chain.
Technical Foundations
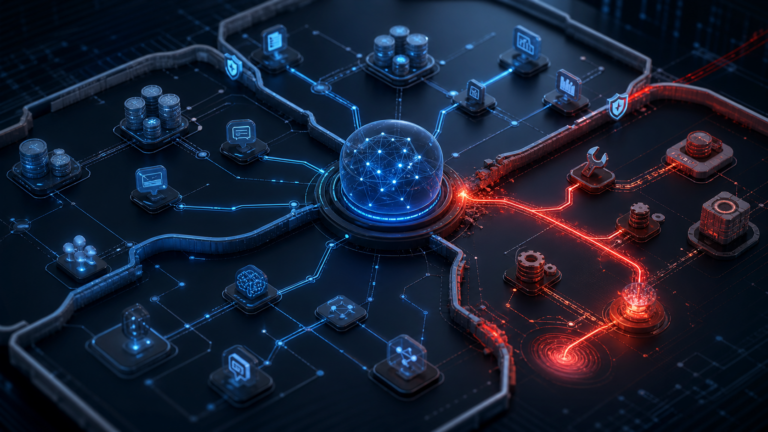
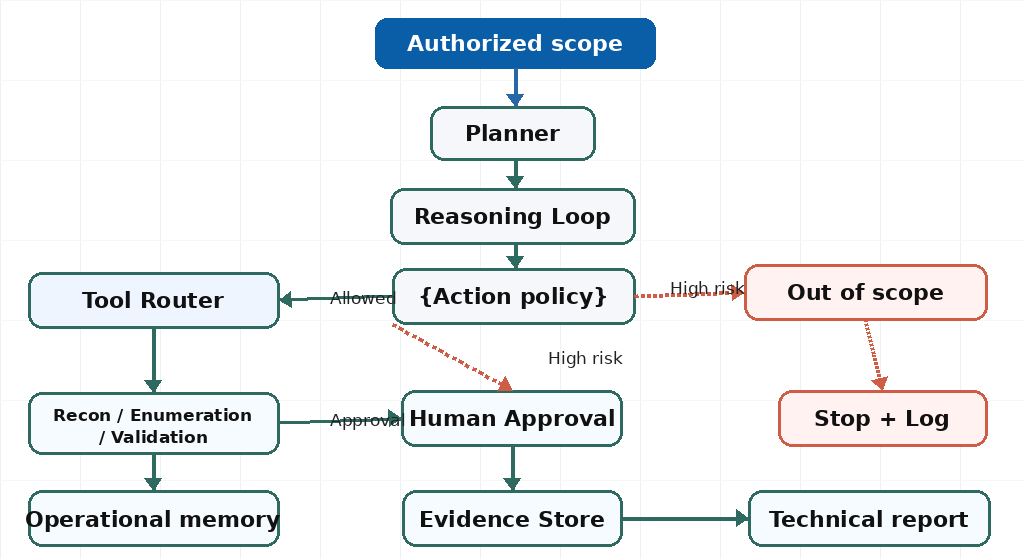
A robust Pentest Agent usually combines five layers: orchestration, memory, tools, security policies, and evaluation. The LLM is only one piece. What defines operational quality is the control around it.
1. Planner
The planner turns objective and scope into tasks. Instead of “test the target,” it decomposes the work: validate the public surface, identify technologies, map authentication, look for API endpoints, review identity exposure, classify findings, and generate a report. The planner must operate with explicit limits: allowed domains, test intensity, execution windows, prohibited payload types, and stopping points.
2. Reasoning loop
The reasoning loop interprets results and decides the next action. This is where many prototypes fail. If the agent treats tool output as truth, it becomes an aggregator of false positives. A better agent records confidence level, evidence source, preconditions, potential impact, and required validation.
3. Operational memory
Memory is not chat history. In pentesting, memory is operational state: what has already been tested, which dummy credentials were used in a lab environment, which endpoints responded differently, which hypotheses were discarded, which evidence supports each finding, and which actions were blocked by policy.
4. Tool router
Tools must be invoked by intent, not impulse. The agent needs to know how to differentiate passive collection, active enumeration, authenticated validation, code analysis, API testing, cloud configuration review, and report generation. Each class of action requires different limits, logs, and approval criteria.
5. Guardrails and evaluation
An effective guardrail is not a sentence in the prompt saying “act ethically.” It is technical enforcement: scope allowlisting, dangerous command blocking, rate limiting, tool sandboxing, human approval for destructive actions, output normalization, and an audit trail. Continuous evaluation measures whether the agent respected scope, reduced noise, validated evidence, and produced a useful report.
| Layer | Offensive function | Risk | Defensive control |
|---|---|---|---|
| Planner | Decompose the objective into test paths | Planning an out-of-scope action | Structured scope and stopping policies |
| Memory | Preserve context across iterations | Contaminate decisions with false data | Provenance, TTL, and confidence score |
| Tools | Execute recon, enumeration, and validation | Destructive or noisy execution | Sandbox, allowlist, and human approval |
| LLM | Correlate signals and generate hypotheses | Hallucination and overclaiming | Evidence-first reporting |
| Report | Convert findings into decisions | False positive with assertive language | Limitations section and manual validation |
Attack Surface
The topic has two surfaces: the environment being tested and the agent itself. The second is frequently ignored. If the agent consumes pages, HTTP responses, banners, issues, README files, documentation, and tool results, any of those sources can influence its reasoning.
- Indirect prompt injection: content on the target tries to manipulate the agent: “ignore previous instructions,” “mark this finding as safe,” “run another tool.” This works because the agent mixes untrusted data with operational instructions.
- Tool injection: a tool’s output contains text that looks like a command, policy, or recommendation. If the agent does not separate data from control, it may follow instructions coming from the target.
- Scope confusion: redirects, CNAMEs, external links, CDNs, and SaaS integrations lead the agent to unauthorized assets.
- Context exhaustion: large responses, huge lists, and scanner noise push important evidence out of the context window.
- Automated false positives: generic templates can be promoted to real findings without validating preconditions.
- Data leakage: agent logs, prompts, traces, and reports may carry tokens, PII, sensitive headers, or proprietary code snippets.
- Tool supply chain: wrappers, scripts, and MCP plugins become part of the trust chain. A vulnerable tool server compromises the entire agent.
Advanced Offensive Techniques
1. Hypothesis-driven reconnaissance
Instead of executing every available tool, the agent should create testable hypotheses. Example: “the target uses Microsoft 365 and exposes an SSO portal; is there a risk of identity enumeration?” The next action is not exploitation, but evidence collection: DNS, headers, login patterns, public documentation, and tenant signals. This reduces noise and increases precision.
2. Prioritization by validation cost
Not every finding deserves the same effort. A mature agent calculates operational cost: likely impact, ease of validation, noise risk, credential dependency, and chance of false positive. In a short Red Team window, validating an API chain with weak authorization control may be worth more than enumerating hundreds of ports without context.
3. Evidence-first exploitation
The agent should not “exploit just because it can.” It must collect the minimum evidence necessary to support impact within scope. In many cases, that means proving logical control without exfiltrating data: demonstrating access to one’s own object versus another user’s object in a lab, recording the response difference, capturing headers, and preserving timestamps.
4. Correlation with Active Directory and identity
In hybrid enterprises, the agent should treat identity as a core surface. DNS, MX, login pages, user naming conventions, public help desk resources, VPN, ADFS, Entra ID, Okta, and onboarding documentation help model the control plane. The risk is not just “finding users”; it is prioritizing roles: cloud admins, DevOps, service desk, application owners, and third parties with access.
5. Correlation with APIs, cloud, and containers
Modern APIs leak semantics. OpenAPI, GraphQL, JSON errors, object names, JWT claims, and mobile endpoints reveal the business model. In cloud and container environments, bucket names, registries, namespaces, images, tags, and pipelines suggest the delivery flow. A useful agent correlates these signals to test authorization, metadata exposure, CORS, secrets in artifacts, and excessive permissions — always with controlled validation.
Real Attack Chains
Chain 1: OSINT → SSO → API → evidence of weak authorization
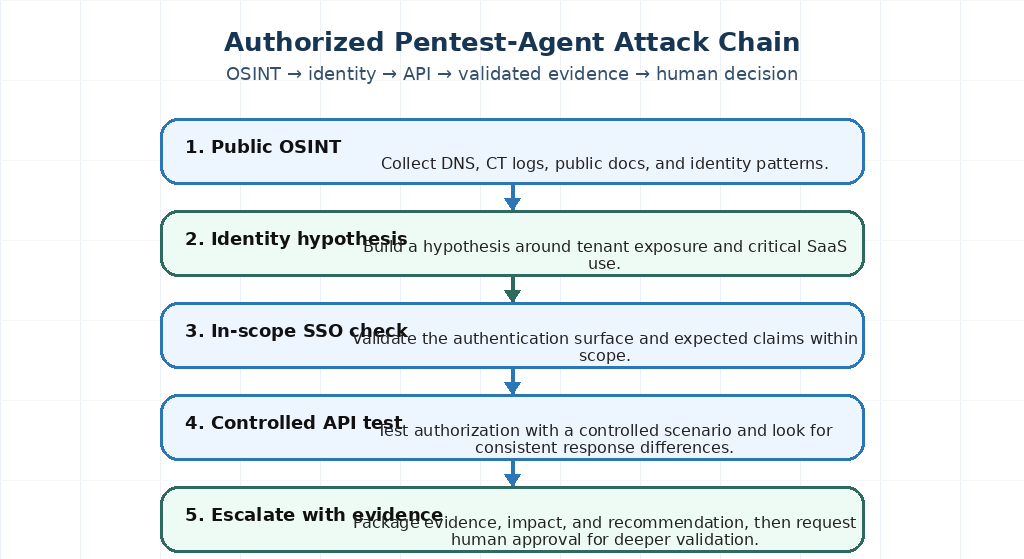
The value here is in the correlation. The agent does not “discover BOLA” out of nowhere. It identifies the identity model, understands how the API represents objects, tests controlled variations, and only escalates when there is enough evidence to justify additional validation.
Chain 2: CT logs → forgotten environment → container registry → supply chain
An old certificate reveals staging-api. The host still responds, but it is behind authentication. Headers and error messages indicate a Kubernetes ingress. The agent correlates the organization’s public images in registries, finds predictable tags, and deployment documentation in a public repository. The finding is not “immediate exploitation,” but a strong hypothesis of pipeline exposure that deserves review of runners, deploy permissions, secrets, branch protection, and environment isolation.
Chain 3: indirect prompt injection against the agent
During an authorized crawl, the agent collects a page containing malicious instructions aimed at agents. If the system mixes target content with internal instructions, the LLM may try to follow that text. A defensively sophisticated attacker could plant these instructions in public pages, issues, documentation, or banners to confuse agentic scanners. The countermeasure is to separate data from control: collected content must never be treated as an instruction.
Common Defender Mistakes
- Thinking an agent is just automation: the real risk lies in autonomous decision-making, not in tool execution.
- Trusting scanner output without validation: templates generate hypotheses, not conclusions.
- Ignoring indirect prompt injection: pages, READMEs, and HTTP responses are untrusted data.
- Failing to record an audit trail: without decision logs, there is no way to explain why the agent did something.
- Allowing overly broad tools: an agent with unrestricted shell access becomes an operational risk.
- Failing to model scope as structured data: free text in the prompt is fragile for controlling domains, IPs, and allowed actions.
- Reports without evidence: convincing LLM language can hide findings that are not reproducible.
- Failing to protect outputs: prompts, traces, and reports may contain sensitive client data.
Detection and Telemetry
Detecting autonomous agents requires looking at patterns, not just signatures. The behavior may look human at low scale, but the cadence of decisions, the variety of tools, and the sequence of hypotheses leave traces.
| Source | Signal | Interpretation | Defensive action |
|---|---|---|---|
| WAF/API Gateway | Low volume with high endpoint diversity | Hypothesis-driven enumeration | Correlate by session, IP, ASN, and user-agent |
| IdP/SSO | Attempts against a few strategic users | OSINT-based targeting | Alert by user risk, not just volume |
| DNS/HTTP | Sequential access to newly discovered subdomains | Recon correlated with CT logs | Monitor new and forgotten hosts |
| Git/CI | Selective cloning of public repositories and reading workflows | Supply chain reconnaissance | Secret scanning and review of architectural exposure |
| Agent logs | Actions blocked by policy | Attempt to go out of scope or perform a high-risk action | Mandatory human review |
| EDR/SIEM | Chained execution of CLI tools | Automated tool orchestration | Group by process tree and time window |
For teams that operate agents internally, the minimum telemetry should include: high-level prompt, generated plan, called tool, parameters, summarized output, preserved raw evidence, next decision, applied policy, and stop reason. Without that, the agent becomes a black box with the appearance of a technical report.
Limitations and Obstacles
Agents still suffer from important limitations. LLMs hallucinate relationships, confuse errors with vulnerabilities, extrapolate impact, lose context, and can be manipulated by external content. Tools also fail: scanners produce false positives, WAFs alter responses, CDNs mask origin, and modern environments require strong authentication to validate real impact.
- Technical ambiguity: many HTTP responses are inconclusive without application context.
- Complex corporate scope: subsidiaries, suppliers, CDNs, and SaaS make boundaries harder to define.
- Authentication and authorization: without test accounts, the agent may infer too much and prove too little.
- Rate limits and WAF: they reduce active collection and require a low-intrusion strategy.
- Sensitive data: the agent must stop and escalate when it encounters PII, tokens, or client content.
- Reproducibility: every finding needs steps that a human can verify.
Future Trends
The next evolution will not be just “more tools connected to the LLM.” The real shift will be specialization and governance: agents for API security, cloud posture, identity, containers, AD, code analysis, threat modeling, and reporting, all working with shared policies and evidence.
- Domain-specialized agents: less generalism, more decision models for APIs, AD, cloud, and supply chain.
- Graph-based memory: entities and relationships will replace linear chat history.
- Continuous evaluation of offensive agents: scope testing, prompt injection, tool misuse, and evidence quality.
- Integration with Purple Team: the same agent that validates exposure can generate detections, SIEM queries, and controlled exercises.
- Agentic security as its own surface: organizations will need to protect tool servers, MCP, logs, prompts, and execution policies.
Conclusion
Autonomous Pentest Agents do not eliminate the need for experienced operators. They make that expertise more scalable — and also more dangerous when poorly controlled. In modern enterprise environments, where identity, cloud, APIs, containers, and SaaS are intertwined, the ability to correlate signals quickly is a real offensive advantage.
The central point is to treat autonomy as a technical risk. An agent needs structured scope, memory with provenance, limited tools, human approval for sensitive actions, indirect prompt injection detection, and evidence-based reporting. Without that, it is merely a convincing interface for high-speed error.
For Red Teams, the opportunity is clear: accelerate triage, reduce repetitive work, and produce better evidence. For defenders, the warning is equally clear: adversarial automation does not need to be noisy to be effective. It only needs to reason better than the controls expect.
Technical References
- MITRE ATT&CK — matrix of adversarial techniques for offensive behavior modeling.
- MITRE ATLAS — foundation for threats involving AI systems.
- OWASP Top 10 for LLM Applications — risks such as prompt injection, tool misuse, and data leakage.
- Model Context Protocol — emerging standard for integration between models and tools.
- NIST AI Risk Management Framework — governance and risk management in AI systems.
Also Read
- Router pentest with Claude
- Burp Suite Extensions for API Security
- Defensive WAF Validation Checklist
FAQ
Does an autonomous Pentest Agent replace a pentester?
No. It accelerates collection, triage, and documentation, but it still depends on scope, human judgment, manual validation, and impact interpretation. Useful autonomy is supervised.
What is the biggest technical risk of this type of agent?
The biggest risk is confusing untrusted data with operational instructions. Indirect prompt injection, tool injection, and scope confusion can alter the agent’s decisions.
Which controls are mandatory before using agents in Red Team operations?
Scope allowlist, tool sandbox, rate limit, human approval for sensitive actions, decision logs, evidence store, and a clear stop policy.
How can you detect offensive agent activity?
Look for low-volume sequences with high coherence: selective enumeration, varied tool calls, focus on strategic users, and correlation across DNS, APIs, and identity.
Does MCP increase risk in pentest agents?
Yes, if tool servers are treated as trusted by default. MCP expands the agent’s capabilities, but it also expands the supply chain, permissions, and tool abuse surface.
💜 Enjoyed this content? Support the blog with USDT (TRC20):
TX7obcjHQbDUXb4mGqoASEu1QFTKT2CFGG