Defensive Corporate OSINT: A Red Team Guide to Mapping Exposure, Identity, and Cloud
Quick summary: Defensive corporate OSINT is not “collecting public information about a company.” That is only the visible layer. In real operations, corporate OSINT is the phase in which the attacker turns scattered signals — DNS, identity, cloud, job postings, repositories, suppliers, metadata, email patterns, technologies, and human behavior — into exploitable hypotheses. A defender who does not simulate this adversarial reading protects only what they know they expose, not what an operator can infer.
Executive Summary
In a mature Red Team, corporate OSINT is the bridge between passive reconnaissance and initial access. The goal is not only to discover subdomains, emails, or technologies; it is to understand how the organization operates, where it outsources trust, which identities have value, which environments are poorly segmented, and which defensive decisions have created blind spots.
The problem is that many companies treat OSINT as a checklist: WHOIS, LinkedIn, Shodan, GitHub, Google dorks, and done. An experienced attacker does something different: they correlate small exposures. An old domain points to a forgotten SaaS platform. A job posting reveals the CI/CD stack. A leaked commit confirms naming conventions. A TLS certificate exposes internal subdomains that migrated to the cloud. A technical LinkedIn profile indicates the EDR tool. A corporate PDF reveals the email pattern, department names, and critical suppliers.
The defensive relevance lies exactly there: OSINT is not an isolated threat. It is the fuel that reduces cost, noise, and uncertainty in the later stages of an offensive chain. The better the attacker’s external intelligence, the less need there is for noisy scanning, the lower the chance of detection, and the greater the precision of the pretext, payload, target selection, and exploitation.
Attacker’s Perspective
An experienced offensive operator does not look at a company as a list of IPs. They see it as an ecosystem of trust: people, domains, suppliers, applications, pipelines, identities, integrations, and processes. The question is not “which port is open?” but “which trust relationship can I turn into movement?”
This difference completely changes collection. Superficial scanning tries to discover what exists. An adversarial operation tries to discover why it exists, who uses it, who administers it, what dependency it creates, and what operational failure likely accompanies that exposure.
For example, finding vpn.empresa.com is useful. But an attacker wants to know more:
- Does the certificate indicate a legacy appliance or a modern solution?
- Does the portal use federated authentication, MFA, or local login?
- Does the ASN belong to the company, a provider, or an old acquisition?
- Are there help desk pages teaching employees how to configure the VPN client?
- Can the users’ email pattern be combined with LinkedIn names?
- Is there evidence of contractors with remote access?
- Does the portal’s visual branding allow for a convincing pretext?
The attacker operates through hypotheses. They do not need certainty at the beginning; they need probabilities. If the company advertises openings for “Azure AD, Intune, Okta, Kubernetes, and GitLab CI,” there is a likely set of surfaces: federated identity, managed devices, exposed pipelines, runners, secrets, cloud groups, SaaS integrations, and developer permissions.
This also explains why OSINT is so powerful against environments with strong perimeter security. The more the company migrates to SaaS, cloud, and identity, the less the classic perimeter matters. The target becomes the control plane: accounts, tokens, permissions, automations, suppliers, and business workflows.
Technical Foundations
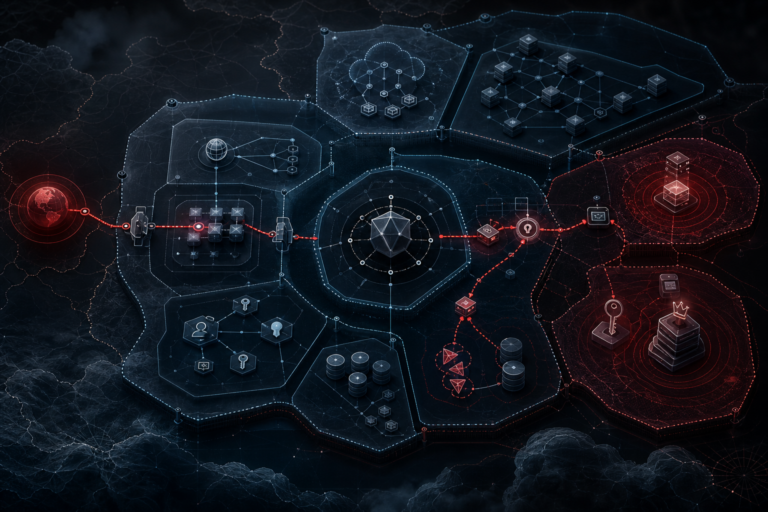
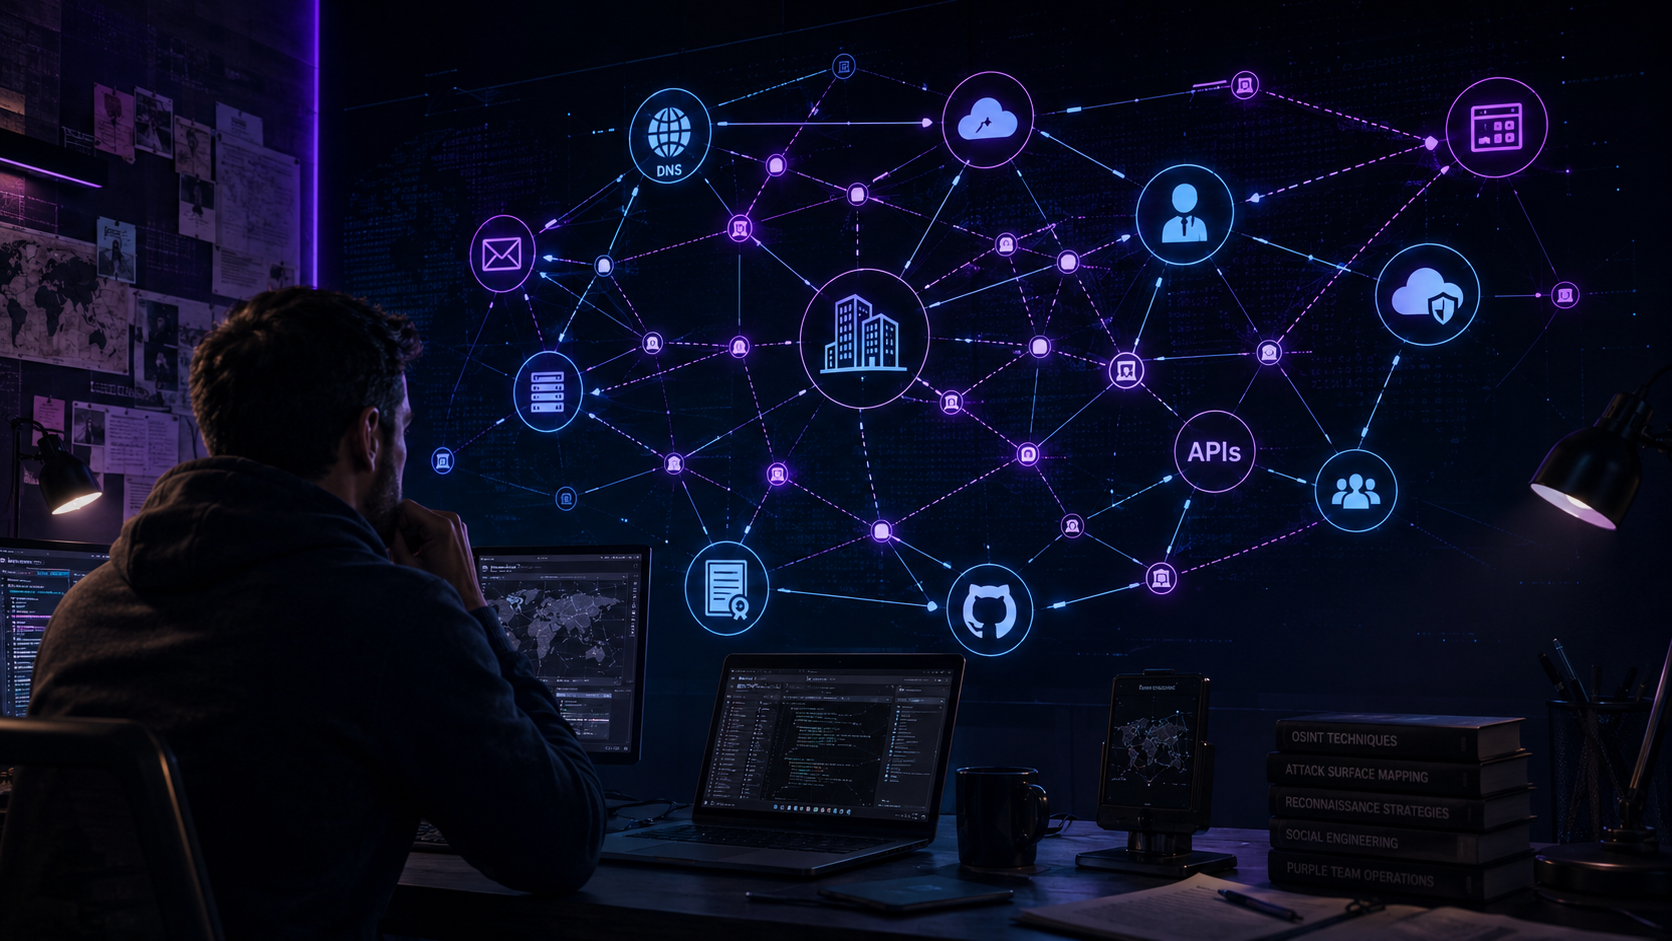
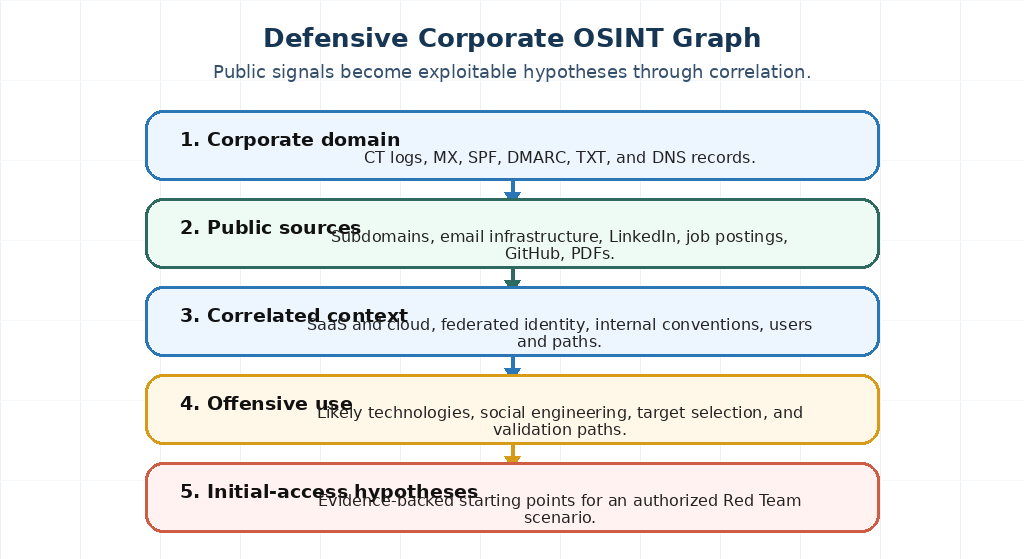
Defensive corporate OSINT should be modeled as a graph. Each node represents an observable element: domain, subdomain, certificate, email address, person, role, repository, package, ASN, IP, technology, supplier, SaaS application, bucket, cloud tenant, API endpoint, or public document. Each edge represents a relationship: “resolves to,” “uses certificate,” “belongs to,” “mentions,” “authenticates with,” “integrates with,” “was created by,” “shares pattern.”
This view is important because most corporate exposures are not critical in isolation. Risk comes from the combination. An orphaned subdomain may be harmless. An orphaned subdomain that points to an abandoned SaaS platform, uses internal environment naming, and appears in public documentation becomes a strong hypothesis for takeover, inventory bypass, or technical social engineering.
1. Identity as an external surface
In modern environments, identity is perimeter. MX, SPF, DMARC, TXT verification records, login pages, SSO providers, tenant URLs, and OAuth integrations expose more than many internal inventories. A domain with records for Microsoft 365, Okta, Atlassian, Slack, GitHub Enterprise, and Cloudflare Access already reveals an approximate map of the control plane.
The reason this works is simple: corporate SaaS depends on public proof of domain ownership. TXT records, CNAMEs, and callback URLs are necessary for legitimate operation. The attacker exploits that same operational transparency to infer dependencies.
2. Certificates as architecture history
Certificate Transparency does not only show current names. It reveals old decisions, migrations, temporary environments, naming patterns, and sometimes systems that should never have had public names. Subdomains such as adfs, vpn, jira, git, sonar, jenkins, grafana, api-dev, staging, and preview help reconstruct the company’s logical topology.
The offensive advantage is not only finding a live host. Even dead names help. They reveal internal vocabulary, area abbreviations, product names, regional patterns, and possible acquired domains. This improves wordlists, pretexts, endpoint fuzzing, and brand recognition in controlled simulated phishing campaigns.
3. Public documents as operational leakage
PDFs, presentations, manuals, public notices, proposals, and whitepapers often carry useful metadata: usernames, local paths, software versions, editing tools, naming patterns, and dates. Even when metadata is cleaned, the content reveals internal structures: responsible areas, system names, suppliers, approval workflows, and language used by the organization.
The attacker uses this to reduce social friction. An email that correctly mentions an internal system, a departmental acronym, or the name of a real supplier seems less generic. For the defender, this means institutional publishing is also an attack surface.
Attack Surface
The corporate OSINT surface should not be treated as only “internet-facing assets.” In Red Teaming, it includes any public data that allows target selection, control inference, pretext building, dependency discovery, or technical uncertainty reduction.
| Source | What it reveals | Offensive abuse | Defensive control |
|---|---|---|---|
| DNS and CT logs | Subdomains, SaaS, old environments | Takeover, enumeration, wordlists | Continuous inventory, orphaned CNAME removal |
| MX/SPF/DMARC | Email providers and anti-spoofing policy | Spoofing, reputation bypass, targeting | Progressive DMARC, lean SPF, aligned DKIM |
| Job postings and LinkedIn | Stack, tools, seniority, teams | Technical pretext, identity selection | Review of language and operational exposure |
| Public GitHub/GitLab | Secrets, code patterns, endpoints | Token abuse, supply chain, API recon | Secret scanning, publication policy |
| Cloud/SaaS | Tenants, buckets, portals, integrations | Account takeover, OAuth abuse, enumeration | CASB, identity logs, app baseline |
| Public documents | Metadata, names, processes, suppliers | Contextual social engineering | Sanitization and pre-publication review |
| Public APIs | Contracts, endpoints, versioning | BOLA/BFLA, enumeration, workflow abuse | Inventory, authz tests, contextual rate limiting |
Active Directory exposed by inference
Even without access to AD, OSINT often reveals its design. Email patterns indicate likely sAMAccountName or UPN formats. ADFS, Azure AD, VPN, and help desk portals indicate the authentication model. Job postings for “GPO,” “SCCM,” “Intune,” “Entra ID,” “hybrid join,” or “ADFS migration” reveal whether the environment is hybrid, cloud-native, or legacy.
This is valuable because identity attacks depend far more on context than on brute force. Knowing that the company uses UPN in the format first.last@domain, that contractors use a different suffix, and that the help desk accepts resets through a specific workflow can guide simulations of password spraying, MFA fatigue, consent phishing, or service desk abuse — always under formal authorization in a legitimate Red Team engagement.
Cloud and APIs as a correlated surface
Cloud environments rarely appear explicitly as “AWS account 123456.” They appear through clues: buckets with brand names, API Gateway endpoints, azurewebsites.net domains, cloudfront.net, firebaseapp.com, herokuapp.com, vercel.app, netlify.app, TXT verification records, and public scripts loaded by the frontend.
The attacker looks for inconsistencies. If the main site is well protected, but an old landing page on Vercel exposes variables, a mobile API allows enumeration, or a staging bucket has permissive CORS, the chain does not need to touch the traditional perimeter. The path runs through shadow IT, integrations, and product environments.
Advanced Offensive Techniques
1. Reconnaissance by delta, not by snapshot
Superficial articles teach you to list subdomains. Better operations monitor change. A new subdomain, a newly issued certificate, an added TXT record, or a published job opening may indicate a project being deployed. New environments tend to have incomplete controls, temporary rules, and exceptions that have not yet been reviewed.
Defenders should think in terms of “exposure through change.” Every relevant public change should trigger a review: a new CNAME, new SaaS, new domain, new bucket, new portal, new mobile app, new email provider, new DMARC policy, or new wildcard certificate.
2. SaaS discovery through verification records
TXT records often reveal integrations: Google Workspace, Microsoft 365, Atlassian, Zendesk, HubSpot, Salesforce, Notion, Slack, GitHub, GitLab, Webflow, Vercel, Netlify, Cloudflare, Mailchimp, and many others. For the attacker, this shows where to look for identities and where a pretext may be plausible.
The technical reason is that SaaS providers need to validate domain ownership to enable email, SSO, branding, callbacks, or publishing. These records are public by design. Defense should not try to hide the inevitable, but reduce abuse: OAuth app review, phishing-resistant MFA, consent logs, restriction of external tenants, and anomalous login monitoring.
3. Low-noise identity enumeration
An operator does not need to fire off thousands of attempts to validate users. They can combine LinkedIn, emails from public breaches, commit authors, PDFs, team pages, events, vendors, and naming patterns. The final list is small, prioritized, and rich in context.
This refinement reduces detection. Instead of generating massive noise, the attacker selects high-value identities: cloud administrators, DevOps, help desk, finance, executives, application owners, apparent service accounts, and third parties with access. Defenders who alert only on volume miss precision attacks.
4. Pipeline and supply chain reconnaissance
Public repositories, packages, Docker images, manifests, package.json files, requirements.txt, pom.xml, Dockerfile, and CI/CD workflows reveal a great deal about the delivery lifecycle. Even without secrets, they show dependencies, registries, CI providers, environment names, and deployment patterns.
In Red Team operations, this can guide supply chain scenarios: internal typosquatting, dependency confusion, abuse of a poorly isolated runner, a malicious pull request in an authorized simulation workflow, token exposure in logs, or excessive permissions in deploy keys. The defensive question is: “Can an external observer infer how our software reaches production?”
5. AI-assisted OSINT: benefit and risk
AI models accelerate correlation: they summarize job postings, extract entities from documents, cluster technologies, suggest relationships, and turn public data into hypotheses. The risk is false confidence. LLMs hallucinate relationships, invent technologies, and may treat coincidence as evidence. In serious operations, AI should help with triage, not decide the truth.
The most interesting defensive use is to create an “adversarial mirror”: feed it only authorized public data and ask what chains an attacker could assemble. The output should be reviewed by human analysts, converted into hypotheses, and validated with evidence. The value lies in the speed of correlation, not autonomy.
Real Attack Chains
Chain 1: public document → identity → SaaS → initial access
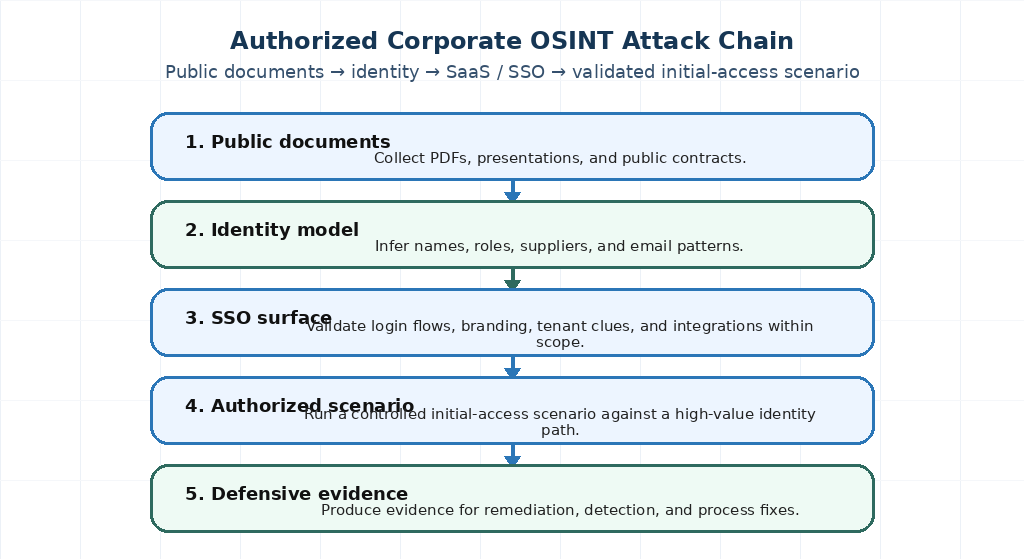
The technical point of this chain is that no individual step seems severe in isolation. Public documents are normal. LinkedIn is normal. SaaS with a public login is normal. The risk emerges when these signals enable a highly precise approach against an identity with relevant access.
Chain 2: CT logs → orphaned subdomain → takeover → brand trust
Subdomain takeover keeps appearing because teams create temporary resources and forget DNS. The attacker finds a CNAME pointing to a provider without an active resource, registers the equivalent resource, and starts serving content under a trusted domain. Even if there is no sensitive data, the trust impact is high: phishing, capture of misconfigured OAuth tokens, payload delivery in a simulation, or bypass of internal allowlists.
The countermeasure is not just “remove old DNS.” It is having a process: record owner, creation date, justification, associated resource, dangling CNAME monitoring, and review when projects are decommissioned.
Chain 3: DevOps job posting → CI/CD stack → public repository → supply chain hypothesis
A job posting mentions GitLab CI, Kubernetes, Helm, Argo CD, and AWS. The organization’s public repositories contain charts and namespace names. A public Docker image uses predictable tags. Even without credentials, the attacker learns the pipeline’s vocabulary. In an authorized exercise, this can become an assessment of runner permissions, merge controls, branch protection, secret masking, OIDC for cloud, and isolation between environments.
Defense usually focuses on secrets. But architecture exposure also matters. It enables the construction of payloads and pretexts that are more compatible with the real environment, increasing the success rate of supply chain scenarios.
Common Defender Mistakes
- Treating OSINT as an annual report. Exposure changes daily. A snapshot ages quickly.
- Ignoring “non-critical” assets. An old subdomain may not contain data, but it may carry brand trust.
- Separating identity from the external surface. Public login, tenant, SSO, and MFA are part of the perimeter.
- Not reviewing institutional publications. PDFs, manuals, and job postings reveal technology and process.
- Monitoring only volume. OSINT-driven attacks are precise and may generate few events.
- Not inventorying SaaS. TXT records and CNAMEs often reveal tools the security team does not track.
- Underestimating vendors. Third parties appear in MX, help desk, job postings, documents, portals, and integrations.
- Leaving DMARC in permissive mode indefinitely. This preserves deliverability, but increases spoofing risk when there is no improvement plan.
Detection and Telemetry
Passive reconnaissance is difficult to detect because the attacker uses public sources. Even so, defenders can observe indirect effects, surface changes, and attempts at active validation. The correct strategy is to combine external monitoring with telemetry from identity, DNS, WAF, email, SaaS, and cloud.
| Layer | Useful signal | Interpretation | Action |
|---|---|---|---|
| DNS | New CNAME/TXT/MX | New SaaS, migration, or shadow IT | Validate owner, risk, and necessity |
| CT logs | New certificate for a sensitive subdomain | New service or temporary environment | Check exposure and access control |
| Identity | Login failures for a small number of strategic users | Selective spraying or account validation | Correlate with source, user-agent, and MFA |
| OAuth/SaaS | Unusual consents | Possible consent phishing | Review app, scopes, and publisher |
| DMARC fail with corporate header_from | Spoofing or a misaligned third party | Adjust SPF/DKIM/DMARC and investigate the source | |
| WAF/API | Low volume on enumeration endpoints | Precise technical reconnaissance | Alert on pattern, not just rate |
| Git | Secret scanning or a new public commit | Exposure of token or architecture | Revoke, rotate, and review the pipeline |
Practical indicators for SOC and Blue Team
- Login failures in executive, DevOps, cloud admin, and help desk accounts, even at low volume.
- Attempts against newly published portals or newly created subdomains.
- Access to documentation endpoints, OpenAPI, Swagger, GraphQL introspection, and legacy static files.
- Unusual queries to password reset, SSO, VPN, webmail, and service desk pages.
- New OAuth applications with broad scopes or an unverified publisher.
- Aggregated DMARC reports indicating third parties sending as the domain without alignment.
- Secret scanning alerts in forks, gists, packages, and employees’ personal repositories.
An often overlooked point: OSINT detection should not rely only on internal tools. The defensive team needs to monitor its own exposure the way an attacker would. That includes CT logs, DNS, GitHub, paste sites, package registries, public cloud assets, app stores, documentation, public leaks, and changes to institutional pages.
Limitations and Obstacles
Corporate OSINT has limits. Not every public piece of evidence is true, current, or relevant. Companies change their stack, job postings copy old descriptions, vendors appear in legacy records, and dead subdomains may not indicate current risk. The classic offensive mistake is turning a hypothesis into a conclusion.
In professional operations, each finding should receive a confidence level:
| Level | Criteria | Example | Operational use |
|---|---|---|---|
| Low | Single, outdated source | 2021 job posting mentioning ADFS | Weak hypothesis |
| Medium | Two independent sources | Microsoft 365 TXT + Entra ID job postings | Plan validation |
| High | Current technical evidence | Active SSO portal + recent certificate | Prioritize authorized testing |
| Critical | Confirmed exploitable exposure | Takeoverable orphaned CNAME | Immediate action |
There are also useful defensive obstacles: phishing-resistant MFA, egress control, SaaS inventory, OAuth review, strong DMARC, branch protection, secret scanning with automatic revocation, metadata protection, secure publishing training, and deprovisioning processes that remove DNS, accounts, and integrations.
Future Trends
Corporate OSINT is changing for three reasons: SaaS expansion, AI-driven automation, and the dissolution of the perimeter. The next generation of adversarial reconnaissance will be less scan-based and more focused on continuous correlation.
- Event-driven continuous OSINT: attackers and defenders will monitor deltas in CT logs, DNS, GitHub, app stores, job postings, and cloud records.
- AI for entity correlation: models will accelerate linking people, technologies, vendors, and assets, but they will require human validation.
- Identity-first recon: the focus will continue shifting from IPs to accounts, tenants, OAuth apps, SSO flows, and permissions.
- Supply chain as a primary source: packages, images, workflows, and integrations will reveal more than service banners.
- Defense through measurable exposure: mature programs will treat external attack surface management and adversarial OSINT as a routine security practice, not as an annual pentest activity.
Conclusion
Defensive corporate OSINT is a discipline of adversarial thinking. The central question is not “what do we publish?” but “what can an operator infer from what we publish?” That inference is what turns seemingly harmless data into attack chains.
In modern corporate environments, the real surface spans Active Directory, Entra ID, Okta, Google Workspace, cloud, APIs, pipelines, containers, vendors, documents, and people. The attacker does not respect org charts or tool boundaries. They follow trust relationships. The defense must do the same.
The practical path is to create a continuous process: inventory public exposure, correlate signals, classify hypotheses, validate risks, fix processes, and feed detection. When executed well, defensive OSINT stops being a list of findings and becomes a way to reduce the adversary’s informational advantage.
Technical References
- MITRE ATT&CK — Active Scanning
- MITRE ATT&CK — Gather Victim Network Information
- MITRE ATT&CK — Gather Victim Identity Information
- OWASP API Security Project
- Microsoft Entra ID sign-in logs
- GitHub Secret Scanning
- RFC 7489 — DMARC
FAQ
Is defensive corporate OSINT different from EASM?
Yes. EASM focuses primarily on inventory and the external exposure of assets. Defensive corporate OSINT includes that, but also correlates people, identity, vendors, documents, SaaS, cloud, APIs, processes, and operational signals to simulate an adversarial reading.
Can OSINT reveal risks even without a technical vulnerability?
Yes. Many chains begin with inference: email pattern, stack, vendor, portal, process, or high-value identity. Even without an exploit, that information improves social engineering, target selection, and abuse of legitimate flows.
How should OSINT findings be prioritized?
Prioritize by likely exploitability, relationship to identity, trust exposure, criticality of the affected process, and current evidence. A current orphaned CNAME is more urgent than a technology mentioned in an old job posting.
Which logs help detect OSINT-based abuse?
Identity, MFA, OAuth consent, WAF, API gateway, DNS, email/DMARC, CASB, Git, secret scanning, and cloud audit logs. The most important thing is correlating low-volume activity with the context of a sensitive target.
Should AI be used in corporate OSINT?
Yes, but as a triage and correlation accelerator, not as a source of truth. Every AI-generated hypothesis must be validated with technical evidence to avoid hallucinations and false conclusions.
💜 Enjoyed this content? Support the blog with USDT (TRC20):
TX7obcjHQbDUXb4mGqoASEu1QFTKT2CFGG